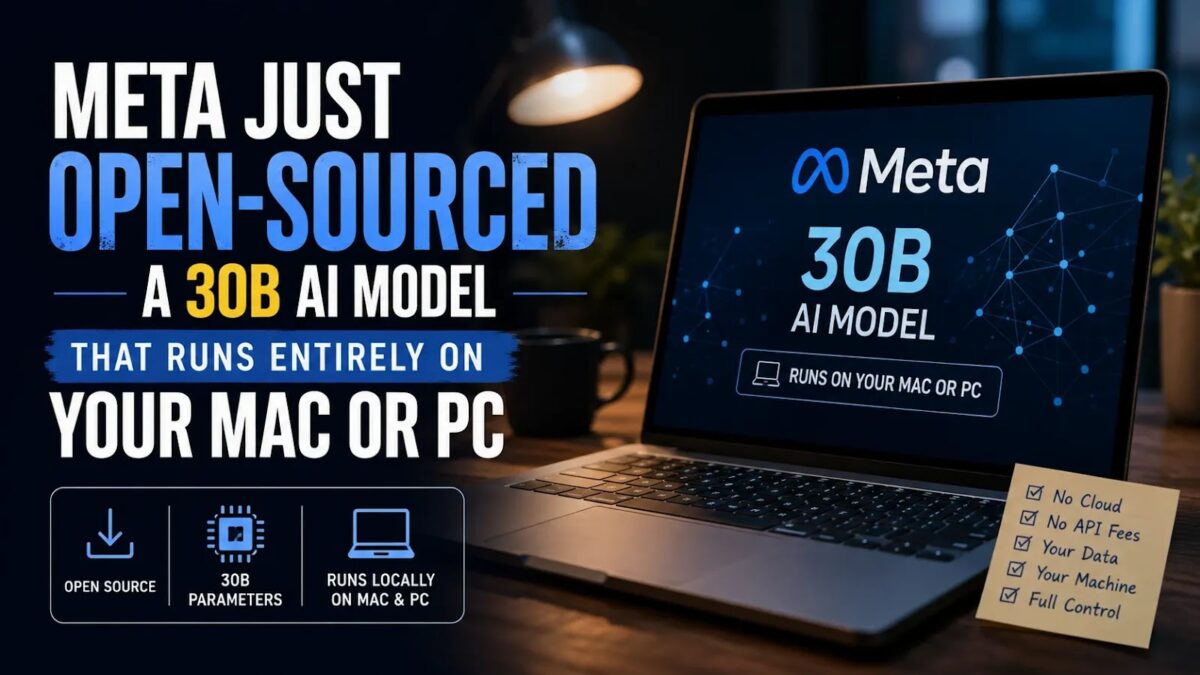
Meta released Muse Glimmer on August 10, 2026 as a 30-billion-parameter open-weight model aimed at local agent workflows. Local execution can reduce dependence on a hosted model, but it does not automatically make every agent action private or safe.

What Meta’s release describes
The release uses an Apache 2.0 license and describes quantized configurations for consumer hardware. Meta says the roughly four-bit language-model weights fit below 20 GB, while the complete runtime also needs memory for other components. Its examples discuss 24 GB or 32 GB configurations. That is not a guarantee that every device with a nominally similar capacity will run every workload well.
Read the safety table precisely
Meta’s model page reports a CI Memories violation score of 26.4 for Glimmer, compared with 12.1 for Gemma4-31B and 53.4 for Qwen3.6-27B; lower is better in that column. Its Siren AgentDojo table reports attack success of 28.4, 25.6 and 40.3 respectively. Glimmer’s 94.2 utility is the utility result in that evaluation, not a universal score for all tasks.
These are vendor-published evaluation results under particular conditions. We have not reproduced them. A benchmark comparison does not establish the probability that your own agent will leak data or make an unauthorized change.
Local inference is only one boundary
An agent can run its model locally while still calling external tools, sending messages or accessing remote accounts. Review the whole workflow: what data it reads, which integrations it can reach and what actions require confirmation. The location of the model weights does not answer those questions.
Start with non-sensitive sample data and read-only tools. Keep outputs and action logs, test an ambiguous instruction and confirm how the process stops. Expand access only when the workflow provides evidence that the added permission is useful and controlled.
What to check before downloading
- The exact model variant and license accompanying it.
- Available memory, software support and the intended context length.
- Whether additional services send data off the device.
- What the agent may change and how you can reverse it.
The earlier claim that Gemma was not intended for local use, a universal speed-up figure and an undated promise about future Spark weights have been removed. This article is a documentation-based explanation, not a local installation test.
Sources and scope
Source check: November 17, 2026. Corrected the broken opening, hardware caveats and benchmark scope; removed unsupported local-use, speed and future-release assertions. This is source-based reporting and editorial analysis, not a hands-on product or investment test.